Metric catalog
Choose a supported metric, prepare the evidence it needs, and interpret its result in context.
Use this catalog when choosing metrics for a test or investigating a result. It lists the 23 metrics currently available in the metric selector and backed by a runtime implementation. The broader in-product Rubric Table is a reference framework and can include more entries; this page intentionally does not reproduce that table. A metric only produces a useful result when the call contains the evidence and setup it needs.
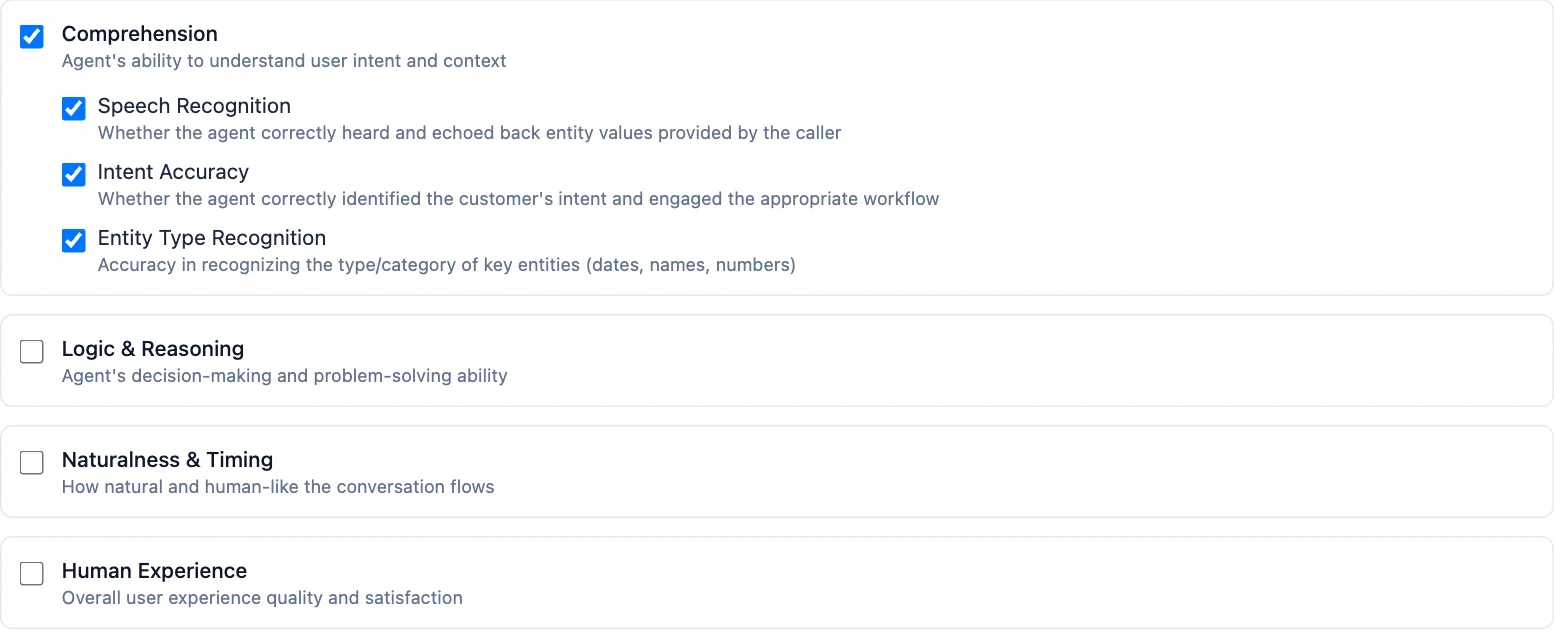
The supported metric selector groups current metrics by rubric; expand a rubric to review and select its metrics.
Choose the right evidence first
Start with the question you want the test to answer, then make that question observable in the scenario. A transcript can support many checks about understanding, decisions, experience, loop/dead-end behavior, and interruption recovery. Timing and overlap checks need call audio. Some checks also need supplied test context, such as the intended workflow or policy.
| If you need to learn about | Start with | Make sure the test includes |
|---|---|---|
| What the agent understood | Comprehension | Known intents, entity types, or values that can be checked from the conversation |
| Whether it made sound decisions | Logic | A multi-turn scenario, plus the relevant workflow or policy when the metric needs one |
| Whether the conversation flowed naturally | Naturalness | Usable audio for timing and overlap metrics; a transcript for Loop and Dead-End Detection or Interruption Recovery |
| How the caller was likely affected | Human Experience | A complete conversation with a clear task outcome and enough caller language to judge it |
For an ordinary normalized result, the product displays a 0–100 score and the guidance in Metrics, scores, and missing results explains the current visual bands. Those bands are not a universal pass rule: use a metric's result alongside the scenario, sample size, and evidence. Response Time, Overlap Time, and Barge-In Stop Time are seconds-based. Talk-Over combines overlap behavior into its own score. Speech Recognition may be presented as a matched fraction and count, including coverage. Several metrics have no universal pass threshold.
If a metric is Needs setup or Not scored, treat that as missing evidence or an inapplicable result—not as a zero. Review the call's recording, transcript, and evidence before changing the agent.
Comprehension
| Metric | What it evaluates | Evidence and setup | Result and caveats |
|---|---|---|---|
| Speech Recognition | Whether the agent heard and repeated known caller values correctly. | Use a voice call with known values, a transcript, and ground truth. Include a natural confirmation or an explicit repeat-back prompt. It can be compared across voice or audio conditions for robustness and bias. | Read the matched fraction/count with its N/A or coverage rate. Formatting differences should not outweigh the underlying value; a missing repeat-back is not proof the value was heard incorrectly. |
| Entity Type Recognition | Whether the agent treated a value as the right kind of thing, such as a date, name, amount, or ID. | Provide annotated entity types and a transcript; observable downstream behavior can strengthen the evidence. Scenario coverage is useful, and robustness/bias comparisons are possible. | Compare recognition by entity type. This is type recognition, not a check that every value was captured exactly. |
| Intent Accuracy | Whether the agent identified the caller's request and entered the appropriate workflow. | Supply intended intents and a transcript. Where actions are visible, use them as supporting evidence; otherwise use a clear confirmation prompt. This metric is not selectable for robustness or bias comparisons. | Read overall and per-intent results together, especially for multi-intent turns. Do not confuse an action's absence with a reliable intent judgment when the conversation never made the action observable. |
Logic
| Metric | What it evaluates | Evidence and setup | Result and caveats |
|---|---|---|---|
| Multi-Step Reasoning | Whether the agent can work through a complex sequence toward the requested outcome. | Use a multi-step transcript with intermediate decisions and a clear expected path. | Interpret the normalized result against the scenario's dependencies; a short, simple call cannot demonstrate complex reasoning. |
| Context Carryover | Whether the agent retains and uses important earlier details. | Put a relevant fact early in a multi-turn scenario and require it later in the transcript. | Look for both correct reuse and unnecessary re-asking. A confirmation can be helpful; it is not automatically a failure. |
| Redundant Steps | Whether the agent avoids repeating questions or actions already resolved. | Use a transcript with a completed detail or action that later becomes relevant. | A lower amount of needless repetition is better, but do not penalize an intentional safety or confirmation step without scenario context. |
| Contradiction Detection | Whether the agent avoids conflicting statements across turns. | Include facts that remain stable long enough to compare in the transcript. | Treat the count or score as a prompt to inspect the conflicting turns. A corrected mistake is different from an unresolved contradiction. |
| Out-of-Domain Detection | Whether the agent recognizes a request outside its supported scope and responds appropriately. | Include a defined out-of-scope request and the expected handoff, refusal, or alternative. | A good result is a safe, helpful boundary—not an attempt to answer every request. |
| Ambiguity Handling | Whether the agent asks for clarification when the caller's intent or detail is unclear. | Put a genuine ambiguity in the transcript and leave enough room for a follow-up. | Judge the clarification in context: asking again after a clear answer is not the same as resolving an ambiguity. |
| Error Recovery | Whether the agent recovers constructively after a misunderstanding or error. | Introduce an observable misunderstanding, correction, or blocked path in the scenario. | Inspect whether the agent acknowledges the issue, corrects course, and continues; a smooth call with no error may not be scorable. |
| Workflow Adherence | Whether the agent follows the required workflow steps in a valid order. | Provide the expected workflow and a transcript that exercises its required steps. | Read the adherence result with per-step evidence. Harmless reordering is not the same as violating a required dependency. |
| Conditional Reasoning | Whether the agent consistently applies caller-stated or implied conditions. | Include a condition or preference in the conversation, ideally with a later turn that requires it. | Compare application per condition. Conflicting caller conditions may require clarification rather than a single "correct" response. |
| Common Sense | Whether the agent catches a syntactically valid input that is implausible in context. | Create a clear impossible or inconsistent input in the scenario and retain the transcript. | Read the catch rate by type of impossibility. Do not count a caller self-correction made before the agent can respond as an agent failure. |
| Policy Enforcement | Whether the agent refuses, escalates, or offers a compliant alternative to a policy-violating request. | Provide extracted, ready policy rules, a violating request, and the expected behavior. | Read enforcement per policy or violation. This tests supplied business rules, not preferences stated only during the call or general plausibility. It is not a Runner Bias or Robustness metric. |
How Conditional Reasoning counts and scores conditions
Conditional Reasoning evaluates a business-role agent's later actions against each caller constraint. It is Not scored when the agent under test is configured as the customer, because the speaker roles no longer match this metric's contract. Its scoring treats the caller's wording as follows:
- Split joined requirements when every part must hold. Keep an either/or choice as one
compoundcondition: satisfying any complete alternative isapplied, and a compound condition is neverpartial. - Count a negative constraint separately from an independent positive constraint. Do not score the caller's overall task goal; for example, in "cancel the table, but keep the cake order," score only the constraint to keep the cake order.
- Count a value supplied in response to an open question when a later action could contradict it. A caller's bare selection from the exact menu of options the agent just offered is a transaction slot, not a separate condition.
- Treat a requirement and its explanation or restatement as one condition unless the two clauses can fail independently. Keep one multi-part slot description, such as "Friday at 7pm," as one condition; matching only one dimension can be
partial. - For an if/then statement, score the requested consequence rather than the antecedent state. If the antecedent is false, refraining from the action is
applied; acting anyway isviolated. - Exclude raw facts, task goals, informational requests, bare transaction slots, out-of-scope requests, transcript artifacts, and duplicate restatements from the denominator.
Each condition is typed as explicit, implicit, compound, or override. Implicit means the constraint must be inferred rather than merely having an explanation; override applies only when the caller replaces a condition stated earlier in the same call.
For each condition, applied contributes 1, partial contributes 0.5, and missed or violated contributes 0. The displayed score is 100 times the mean contribution across scored conditions. Partial means the agent honored a condition incompletely or lost it later, missed means an opportunity existed but the response did not settle compliance, and violated means the agent proposed or performed something the condition ruled out. A call with no scorable conditions produces Not scored, not zero.
Naturalness
| Metric | What it evaluates | Evidence and setup | Result and caveats |
|---|---|---|---|
| Response Time | Time from the caller finishing speech to the agent beginning its response. | Use a voice call with usable audio; clean and stressed audio can be compared for robustness and bias. | Read seconds, not the ordinary 0–100 visual bands. Inspect the timing distribution and the turn where a delay occurred. |
| Barge-In Stop Time | How quickly either participant stops after the other interrupts. | Use two-channel call audio and include interruption opportunities in either direction. It can be compared under audio stress. | Read the aggregate response time in seconds across agent-interrupted and caller-interrupted events. A call without a detected interruption does not establish this behavior. |
| Overlap Time | How long the parties speak at the same time. | Use call audio with enough turn-taking to detect overlap; varied audio conditions can support robustness and bias comparisons. | Read seconds and inspect the overlapping segment. Brief acknowledgements can have a different effect from disruptive competing speech. |
| Talk-Over | Whether the agent speaks over a caller who is still talking. | Use call audio and include natural pauses or overlap opportunities; compare under stress when relevant. | This is a combined Talk-Over score, not a substitute for reviewing individual overlap moments. It is distinct from a caller interrupting the agent. |
| Loop and Dead-End Detection | Whether the conversation becomes repetitive or fails to reach a useful close. | Use a transcript with a task resolution or closing sequence. | Investigate the repeated turns behind the result; a purposeful recap or a courteous closing is not automatically a loop. |
| Interruption Recovery | Whether the agent stops, addresses an interruption, and resumes or adapts the thread appropriately. | Include an observable interruption in the transcript. This metric is transcript-only; unlike the audio timing and overlap metrics, it does not require call audio. | Read the result as a sequence—stop, address, then resume or adapt. A single interruption does not always require returning to the previous script. |
Human Experience
| Metric | What it evaluates | Evidence and setup | Result and caveats |
|---|---|---|---|
| Customer Experience | A predicted, evidence-backed view of satisfaction and task-relative effort. | Use a complete transcript with a clear outcome; a voice call can add context, but raw audio features are not required. | Read the 0–100 combined result with predicted satisfaction and effort where shown. It is a proxy, not a customer survey, and has no universal pass threshold. |
| Task Success Rate | Whether the conversation completed the caller's intended task. | Define the intended outcome and use a transcript that shows whether it was reached. | Read the percentage with the task definition and partial outcomes in mind. A completed step is not necessarily a completed customer goal. It is not selectable in Runner Bias or Robustness workflows. |
| Sentiment Progression | Whether the caller's sentiment improved, stayed stable, or worsened over the conversation. | Use available call audio from the beginning and end; when audio is unavailable, the result may rely on transcript evidence. | Interpret direction and the call context rather than a universal threshold. A caller can begin frustrated, and a stable outcome can still be appropriate. |
Limitations and next steps
- The catalog describes supported metrics, not a promise that all 23 apply to every call, test mode, or evidence set.
- A single run is a lead for investigation. Use multiple representative scenarios before drawing a broad conclusion, and keep the scenario, audio conditions, and expected outcome comparable.
- Robustness and bias are ways to compare selected metrics across conditions or groups; they are not standalone metrics in this selector.
- If you vary cohorts while reviewing Policy Enforcement or Task Success Rate, that is manual cohort analysis, not Runner Bias.
- Result labels and evidence availability can change when audio, transcript, required policy, workflow, or scenario context is missing.
When a supported metric becomes available after a call was recorded, re-evaluate the existing run if its saved evidence meets the metric's requirements. To collect new evidence, create a scenario, run a single test, and review the evidence behind any unexpected result.